I Built an AI Agent That Files ServiceNow Incidents Autonomously
Ravi Singhal
19 February 2026
10 min read
How it works, and what the platform can actually be made to do
💡 TL;DR: A Kubernetes agent that uses an in-cluster Ollama LLM to detect failures, correlate root causes, and file ServiceNow incidents — autonomously. Zero API keys. Zero thresholds. One command to run locally. Free developer instance included.
Most developers think of ServiceNow as "that ticketing thing." That's a miss.
In January 2025 ServiceNow shipped a native AI agent runtime — AI Agent Studio + AI Agent Orchestrator — enabling developers to build and compose autonomous multi-step agents directly on the platform.
That's not a ticketing system. That's workflow infrastructure with serious AI primitives.
Here's what I built on top of it, and what broke.
🧩 Why Developers Should Care
The interesting part isn't the UI. It's the Table API.
Every record (incidents, CMDB items, change requests, tasks) is accessible via REST:
POST   /api/now/table/incident          → create
GET    /api/now/table/cmdb_ci           → query config items
PATCH  /api/now/table/incident/{sys_id} → resolve
If you can call HTTP, you can integrate. There is no SDK and no proprietary agent. A developer instance is free, from developer.servicenow.com — full admin access, no credit card, ready in 5 minutes.
🤖 What ServiceNow Shipped in 2025 (A Lot)
The platform shipped two major releases this year. Both matter for developers.
Yokohama (March 2025) — Native AI agent runtime
AI Agent Studio + Orchestrator — build custom agents in natural language; the Orchestrator lets teams of agents collaborate across IT, HR, and CRM, handing off tasks end-to-end. Available to all Pro Plus and Enterprise Plus customers.
GitHub MCP Integration — ServiceNow Build Agent connects to GitHub's Model Context Protocol server, giving agents live access to issues, PRs, and discussions. Community-built MCP servers also let any AI model (Ollama, Claude) query and update ServiceNow records via natural language.
"2026 is the year of agentic collaboration in the enterprise." — Amit Zavery, President & CPO, ServiceNow
Zurich (Q4 2025) — The developer tooling leap
This is the release that should make developers sit up. Zurich shipped changes that bring ServiceNow development into the modern era:
- 🔀 Developer Sandboxes with Git — isolated per-developer environments with branch/PR/code review workflows. No more "two people edited the same flow and one overwrote the other."
- 🔧 Build Agents for CI/CD — integrates with Jenkins, GitHub Actions, and Azure DevOps. Fragile update sets are finally replaceable with proper deployment pipelines.
- 🪝 Webhooks & External Triggers in Flow Designer — flows can now listen on REST/webhook endpoints. A Kubernetes event, a Datadog alert, or a GitHub Actions run can trigger a ServiceNow workflow directly — no polling, pure event-driven.
- ⚡ ES2021 + async/await — modern JavaScript in scoped scripts; non-blocking external API calls without workarounds.
- 🔍 Flow Debugging with full execution trace — step-by-step visibility into which conditions passed, what data transformed where. The days of blind flow failures are gone.
"AI is doing much more than just assisting. It's driving decisions, building interfaces, connecting systems, and adapting to business logic in real time." — ServiceNow Zurich release blog
The webhook trigger feature is particularly relevant to this architecture: instead of the agent polling via REST, Kubernetes could push events directly into a Flow Designer endpoint — pure event-driven, zero lag.
🔭 Australia (Q2 2026) — What's coming next
ServiceNow's upcoming Australia release (the platform moves to country names after Z) has an Early Release Program open now — 8+ weeks of early access before general availability. Key additions include Cloud Governance Suite, Operational Technology Management (OT/IoT security), and a full migration of legacy analytics to the new Platform Analytics engine. If you build on ServiceNow, worth registering at the Early Release Program.
🚨 The 2AM Scenario
A node develops DiskPressure. Pods evict. A critical deployment hits 0 replicas.
| ❌ Without | ✅ With this agent | |
|---|---|---|
| Detection | Alert fires | Auto-detected within 15 min |
| Response | Engineer woken up, form to fill | Two incidents created — P1 + P2 |
| Incident quality | Cluster: unknown | Name, namespace, error, timestamp — pre-filled |
| Documentation | 25 min in | Instant |
The on-call engineer wakes up to a routable, context-rich ticket. Their job: fix the problem, not administer paperwork at 2AM.
⚙️ The Architecture: LLM as the Detector, Not Just the Enricher
The Ollama agent (llama3.2:3b or qwen2.5:7b, running in-cluster) doesn't post-process rule-based alerts — it drives the entire observation loop:
🔍 Observes:  list_nodes → list_pods → list_deployments → get_events
🧠 Reasons:   "DiskPressure on node-3 caused the evictions. Crash-loop on payment-api is separate."
⚡ Acts:       get_open_incidents() → create_incident(P1) → create_incident(P2) → resolve_incident(stale)
✅ Finishes:  "Found 3 issues. Created 2 incidents, resolved 1 stale."
No hard-coded thresholds. The LLM decides what's a real problem. One restart = noise. Zero replicas = P1.
What an LLM-authored incident looks like
Instead of:
Container memory-hog in prod/payment-api was OOMKilled
The engineer gets:
Summary — Container
memory-hogterminated by Linux OOM killer; memory exceeded configured 32Mi limit.Root Causes — Likely unbounded in-memory cache growth or recent dependency upgrade with memory leak.
Remediation —
kubectl describe pod payment-api-7f8d9 -n prod→ confirm OOMKilled → raise limit to 128Mi → review recent merges.Verification — Restart count drops to zero,
kubectl top podstabilises below new limit.
A briefing from a senior SRE. Written before you open your laptop.
🏗️ Three-Layer Architecture
┌──────────────────────────────┐
│  🤖 Ollama (in-cluster)      │  ← Observe → Reason → Act → Finish
│  llama3.2:3b / qwen2.5:7b   │    No egress · No API key · Open-source model
└──────────────┬───────────────┘
               │ expert incidents · auto-resolutions
┌──────────────▼───────────────┐
│  📋 ServiceNow                │  ← Routing · SLAs · CMDB · audit trail · Now Assist
└──────────────┬───────────────┘
               │ governed · structured · traceable
┌──────────────▼───────────────┐
│  ☸️  Kubernetes API           │  ← Raw state: pods · nodes · deployments · events
└──────────────────────────────┘
🔨 What's in the Open-Source Repo
| # | Component | Detail |
|---|---|---|
| 1 | Python microservice | Kubernetes Deployment, REST API via Table API |
| 2 | Agentic LLM loop | Ollama tool-use: observe → reason → act → finish |
| 3 | Intelligent dedup | LLM queries open incidents before creating — no duplicates |
| 4 | Auto-resolution | LLM closes stale incidents when conditions clear |
| 5 | Rule-based fallback | Full pipeline with zero LLM (restart > 5, phase = Failed) |
| 6 | CMDB sync | Agent registers itself as a Configuration Item |
| 7 | CronJob scanner | Periodic agentic scans, all namespaces |
| 8 | Helm chart | Prod-grade deployment with secrets management |
| 9 | /metrics |
Scan counts, incident rates, agent_turns — Prometheus format |
| 10 | setup-dev.sh |
One command: kind cluster + podman build + Ollama + port-forward |
💥 Chaos Demo: See It Create Real Incidents
demo/inject_failures.py deploys broken workloads and you watch incidents appear in ServiceNow in real time.
| Scenario | Failure | Type |
|---|---|---|
| 🔴 A | Pod exits 1 + restartPolicy: Never |
pod_failure |
| 🟠 B | Bad image tag → 0/2 replicas | deployment_unavailable |
| 🟡 C | 200MB alloc vs 32Mi limit → OOMKill | oom_killed |
| 🔵 D | Exits every 2s → restartCount > 5 | crash_loop |
The result:
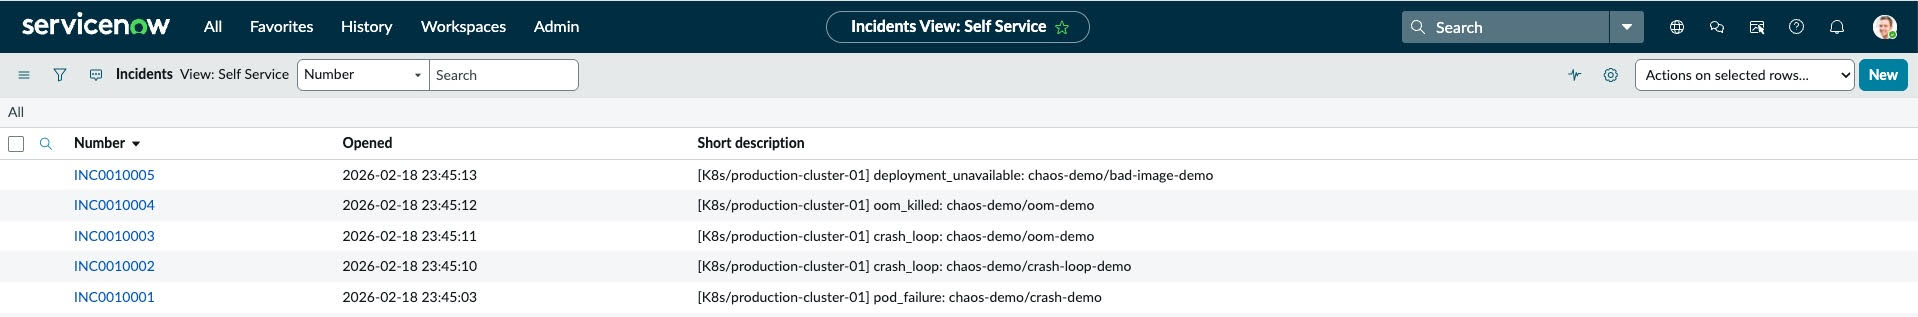 Five incidents filed automatically — pod_failure, crash_loop (×2), oom_killed, deployment_unavailable.
🆓 No instance yet? developer.servicenow.com → Request Instance → your own
https://devXXXXX.service-now.comin minutes. No credit card. (PDIs hibernate — click Wake Instance if you get a 503.)
# Spin up everything locally (kind + podman + Ollama, fully automated)
./setup-dev.sh \
  --snow-url  https://devXXXXX.service-now.com \
  --snow-user admin \
  --snow-pass your-password \
  --with-ollama

# Run the chaos demo
python3 demo/inject_failures.py --agent-url http://localhost:8080

# Tear down
./setup-dev.sh --teardown
⚠️ Pitfalls That Will Burn You
❌ No deduplication — a 15-min CronJob with no dedup = 96 duplicate tickets per day for one stuck pod.
❌ Namespace-scoped only — use cluster-wide
/api/v1/pods, not/api/v1/namespaces/{own}/pods.
❌ Plaintext Secrets — Kubernetes Secrets are base64, not encrypted. Use HashiCorp Vault or Sealed Secrets in prod.
❌ No retry/backoff — ServiceNow has maintenance windows.
429and5xxwill happen. Handle them.
❌ Monitoring kube-system — system pods restart legitimately. Exclude them or you'll drown in noise.
🎯 The Takeaway
If you build infrastructure tooling, write SRE automation, or work on anything that generates operational events, ServiceNow is worth 30 minutes of your time.
Not because you need to become a ServiceNow developer. Because:
- The REST API is clean and well-documented
- There's a free instance you can have in 5 minutes
- The AI agent runtime shipped in 2025 is genuinely interesting
- The CMDB gives agents the structured enterprise context they need to make good decisions
AI agents need context. Context lives in workflows. ServiceNow owns the workflow layer.
$13.3B revenue. 21% growth. Git-integrated dev sandboxes. Webhook triggers. CI/CD Build Agents. Native agentic runtime. And an Australia release around the corner.
That's not a ticketing system. That's infrastructure worth knowing.
📦 Full code at github.com/lake-of-dreams/servicenow-k8s-integration — Python microservice, Helm charts, Ollama manifests, chaos demo, and one-command setup.
💬 Building agentic workflows on enterprise platforms? Using local models in production? I'd love to hear what's working in the comments.
#ServiceNow #Kubernetes #AIAgents #DevOps #OpenSource #Ollama #SRE #PlatformEngineering #CloudNative #BackendDevelopment
Ravi Singhal
Principal Engineer (Executive Director)
Building transformative software solutions through innovative thinking and technical excellence.
© 2026 Ravi Singhal. All rights reserved.